2026
REChart: Reasoning-Efficient Chart Editing with Large Reasoning Models
Yuanbang Liu, , Yihan Hou, Qiong Luo, Wei Zeng
Under review.
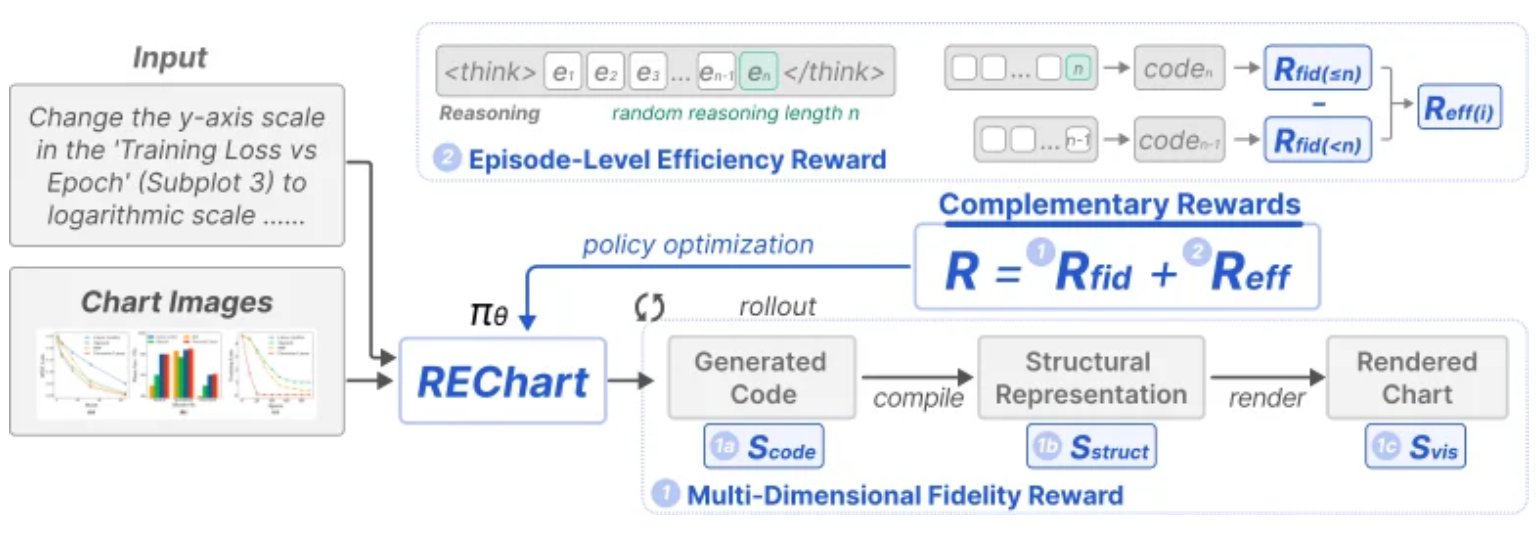
Chart editing requires inferring and modifying visualization code from a reference chart image based on an editing instruction, challenging fine-grained visual reasoning, instruction following, and executable code synthesis capabilities of MLLMs. Large reasoning models (LRMs) with extended Chain-of-Thought (CoT) reasoning are suitable for tackling such complex multimodal tasks. However, our preliminary study reveals an ``inverted-U'' relationship between reasoning length and chart-editing performance: Excessive reasoning often leads to ``overthinking,'' where models drift toward hallucinated visual details or get stuck in redundant reasoning loops. To address the gap, we introduce REChart, a two-stage training framework that provides process-level supervision over intermediate reasoning steps, improving both editing fidelity and reasoning efficiency. First, we synthesize 200k high-quality reasoning trajectories for supervised fine-tuning from a large image-instruction-code pool, using a role-specialized agentic Reason-Score-Refine workflow that iteratively refine the chart code toward higher quality. Second, we optimize the model via reinforcement learning with two complementary rewards: a fidelity reward evaluating code correctness, visual fidelity, and structural consistency, and an efficiency reward that assigns each rollout a random thinking budget, truncates the reasoning process, and credits the final reasoning segment according to its contribution to the output. On the ChartEdit and ChartMIMIC benchmarks, our model achieves state-of-the-art chart-editing performance among open-source models of comparable scale, while mitigating overthinking and reducing average reasoning token usage by 79.0% under a maximum thinking budget of 16,384 tokens compared with the base model.
REChart: Reasoning-Efficient Chart Editing with Large Reasoning Models
Yuanbang Liu, , Yihan Hou, Qiong Luo, Wei Zeng
Under review.
Chart editing requires inferring and modifying visualization code from a reference chart image based on an editing instruction, challenging fine-grained visual reasoning, instruction following, and executable code synthesis capabilities of MLLMs. Large reasoning models (LRMs) with extended Chain-of-Thought (CoT) reasoning are suitable for tackling such complex multimodal tasks. However, our preliminary study reveals an ``inverted-U'' relationship between reasoning length and chart-editing performance: Excessive reasoning often leads to ``overthinking,'' where models drift toward hallucinated visual details or get stuck in redundant reasoning loops. To address the gap, we introduce REChart, a two-stage training framework that provides process-level supervision over intermediate reasoning steps, improving both editing fidelity and reasoning efficiency. First, we synthesize 200k high-quality reasoning trajectories for supervised fine-tuning from a large image-instruction-code pool, using a role-specialized agentic Reason-Score-Refine workflow that iteratively refine the chart code toward higher quality. Second, we optimize the model via reinforcement learning with two complementary rewards: a fidelity reward evaluating code correctness, visual fidelity, and structural consistency, and an efficiency reward that assigns each rollout a random thinking budget, truncates the reasoning process, and credits the final reasoning segment according to its contribution to the output. On the ChartEdit and ChartMIMIC benchmarks, our model achieves state-of-the-art chart-editing performance among open-source models of comparable scale, while mitigating overthinking and reducing average reasoning token usage by 79.0% under a maximum thinking budget of 16,384 tokens compared with the base model.
DKMap: Interactive Exploration of Vision-Language Alignment in Multimodal Embeddings via Dynamic Kernel Enhanced Projection
Yilin Ye, , Yu Zhang, Zikun Deng, Wei Zeng
IEEE Transactions on Visualization and Computer Graphics (VIS 2025)
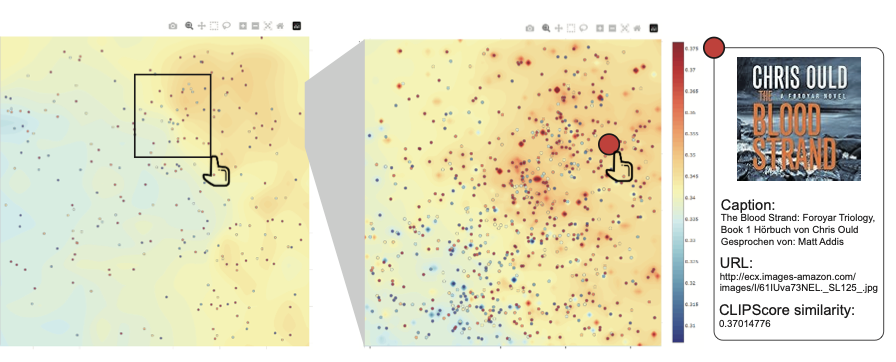
DKMap, a novel DR visualization technique for interactive exploration of multimodal embeddings through Dynamic Kernel enhanced projection.
DKMap: Interactive Exploration of Vision-Language Alignment in Multimodal Embeddings via Dynamic Kernel Enhanced Projection
Yilin Ye, , Yu Zhang, Zikun Deng, Wei Zeng
IEEE Transactions on Visualization and Computer Graphics (VIS 2025)
DKMap, a novel DR visualization technique for interactive exploration of multimodal embeddings through Dynamic Kernel enhanced projection.
ColorConceptBench: A Benchmark for Probabilistic Color-Concept Understanding in Text-to-Image Models
, Yihan Hou, Yu Xiao, Guosheng Hu, Wei Zeng
Under review.
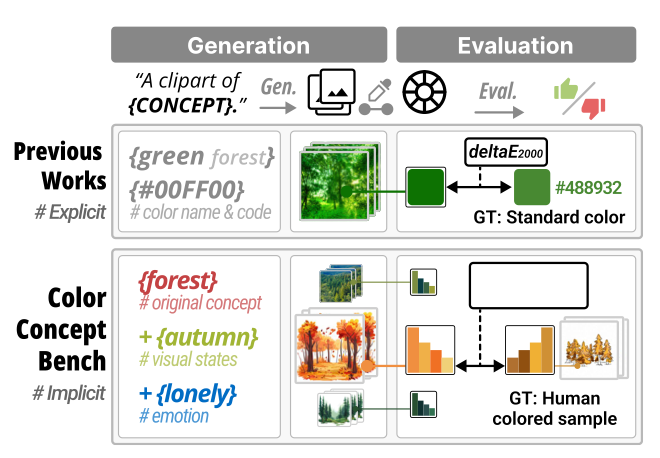
ColorConceptBench, a new human-annotated benchmark to systematically evaluate color-concept associations through the lens of probabilistic color distributions. ColorConceptBench moves beyond explicit color names or codes by probing how models translate 1,281 implicit color concepts using a foundation of 6,584 human annotations.
ColorConceptBench: A Benchmark for Probabilistic Color-Concept Understanding in Text-to-Image Models
, Yihan Hou, Yu Xiao, Guosheng Hu, Wei Zeng
Under review.
ColorConceptBench, a new human-annotated benchmark to systematically evaluate color-concept associations through the lens of probabilistic color distributions. ColorConceptBench moves beyond explicit color names or codes by probing how models translate 1,281 implicit color concepts using a foundation of 6,584 human annotations.
2025
SceneWeaver: A Multi-Agent Collaborative System for 3D Scene Creation in Video Games
Rong Huang, , Bingchuan Jiang, Wei Zeng
Proceedings of the 18th International Symposium on Visual Information Communication and Interaction (VINCI 2025)
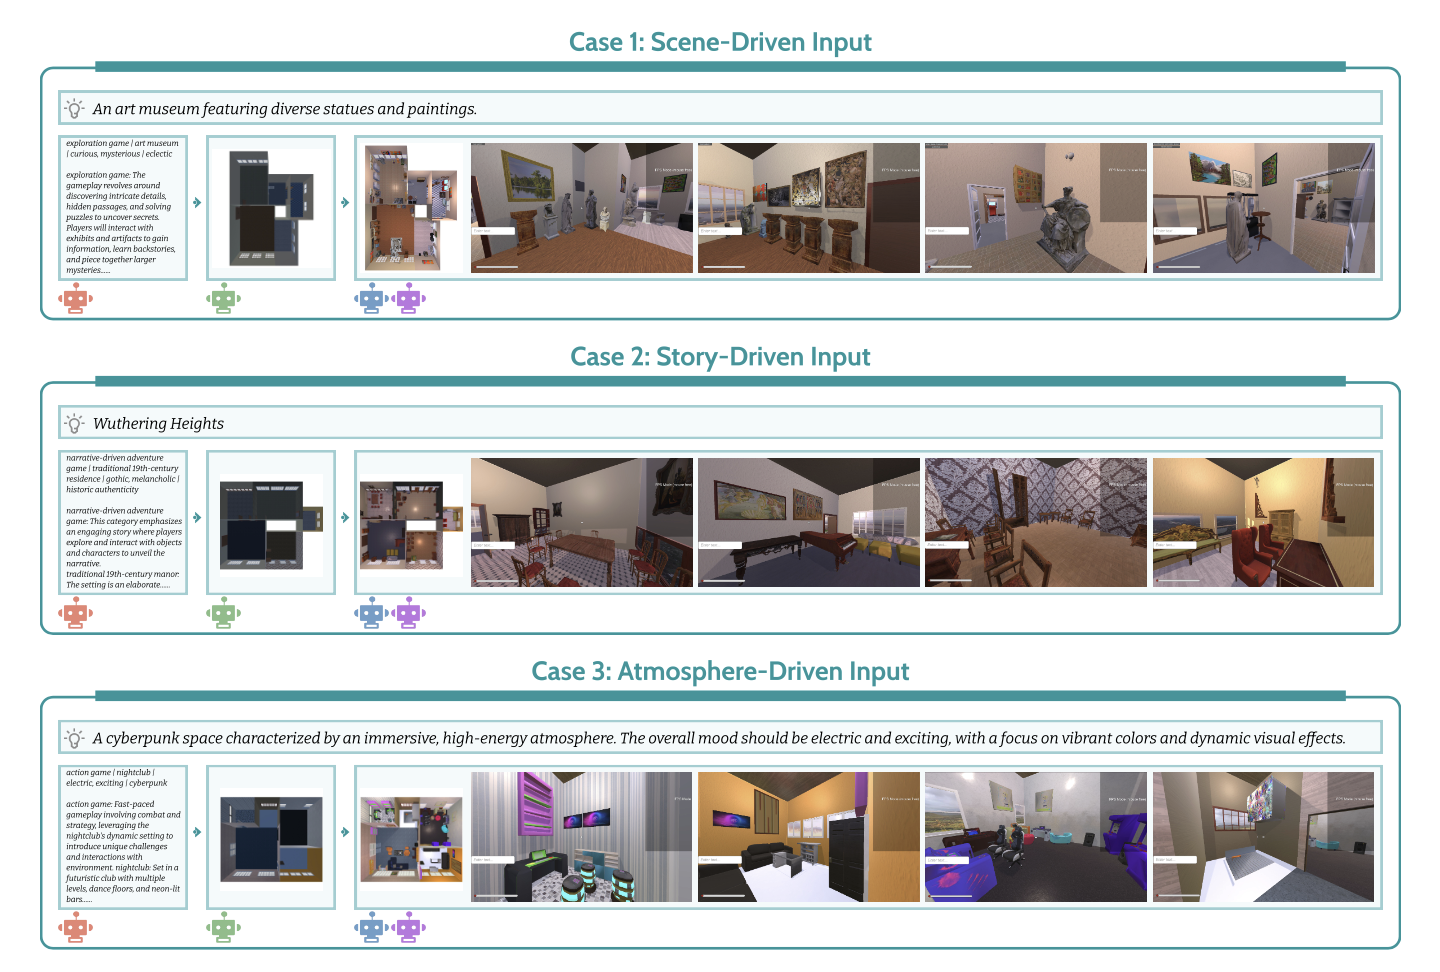
SceneWeaver, a 3D scene creation system that utilizes a multi-agent collaborative framework with large language models (LLMs) assigned to manage text parsing, floorplan design, object selection, and scene composition.
SceneWeaver: A Multi-Agent Collaborative System for 3D Scene Creation in Video Games
Rong Huang, , Bingchuan Jiang, Wei Zeng
Proceedings of the 18th International Symposium on Visual Information Communication and Interaction (VINCI 2025)
SceneWeaver, a 3D scene creation system that utilizes a multi-agent collaborative framework with large language models (LLMs) assigned to manage text parsing, floorplan design, object selection, and scene composition.
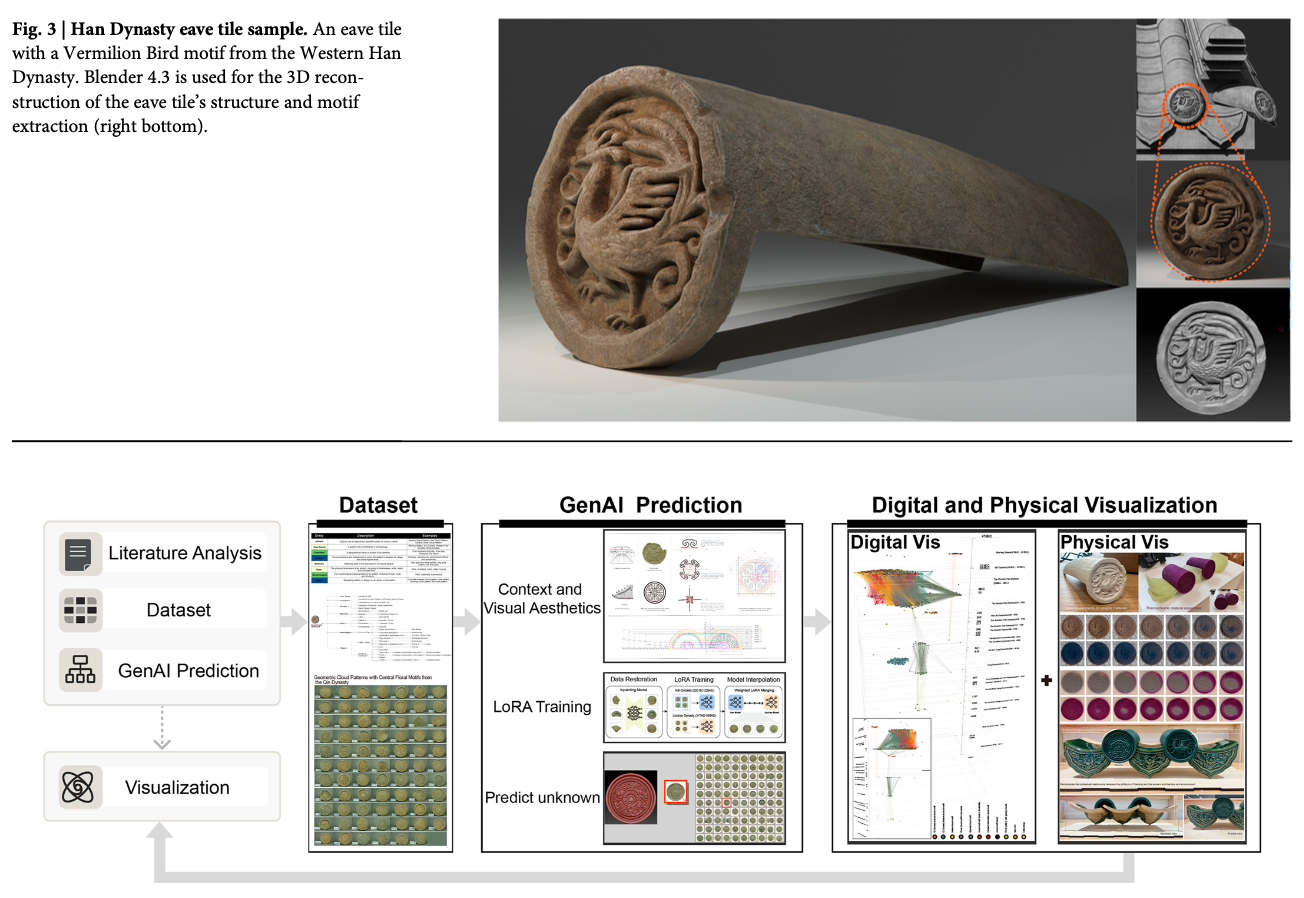
Embodied heritage by integrating digital and physical visualization of eaves tiles to display cultural heritage kinship
Jian Yu, Yilin Ye, Chen Tang, Yuanbang Liu, , Jingxue Feng, Kaihao Zhang, Wei Zeng
npj Heritage Science
Embodied heritage by integrating digital and physical visualization of eaves tiles to display cultural heritage kinship
Jian Yu, Yilin Ye, Chen Tang, Yuanbang Liu, , Jingxue Feng, Kaihao Zhang, Wei Zeng
npj Heritage Science
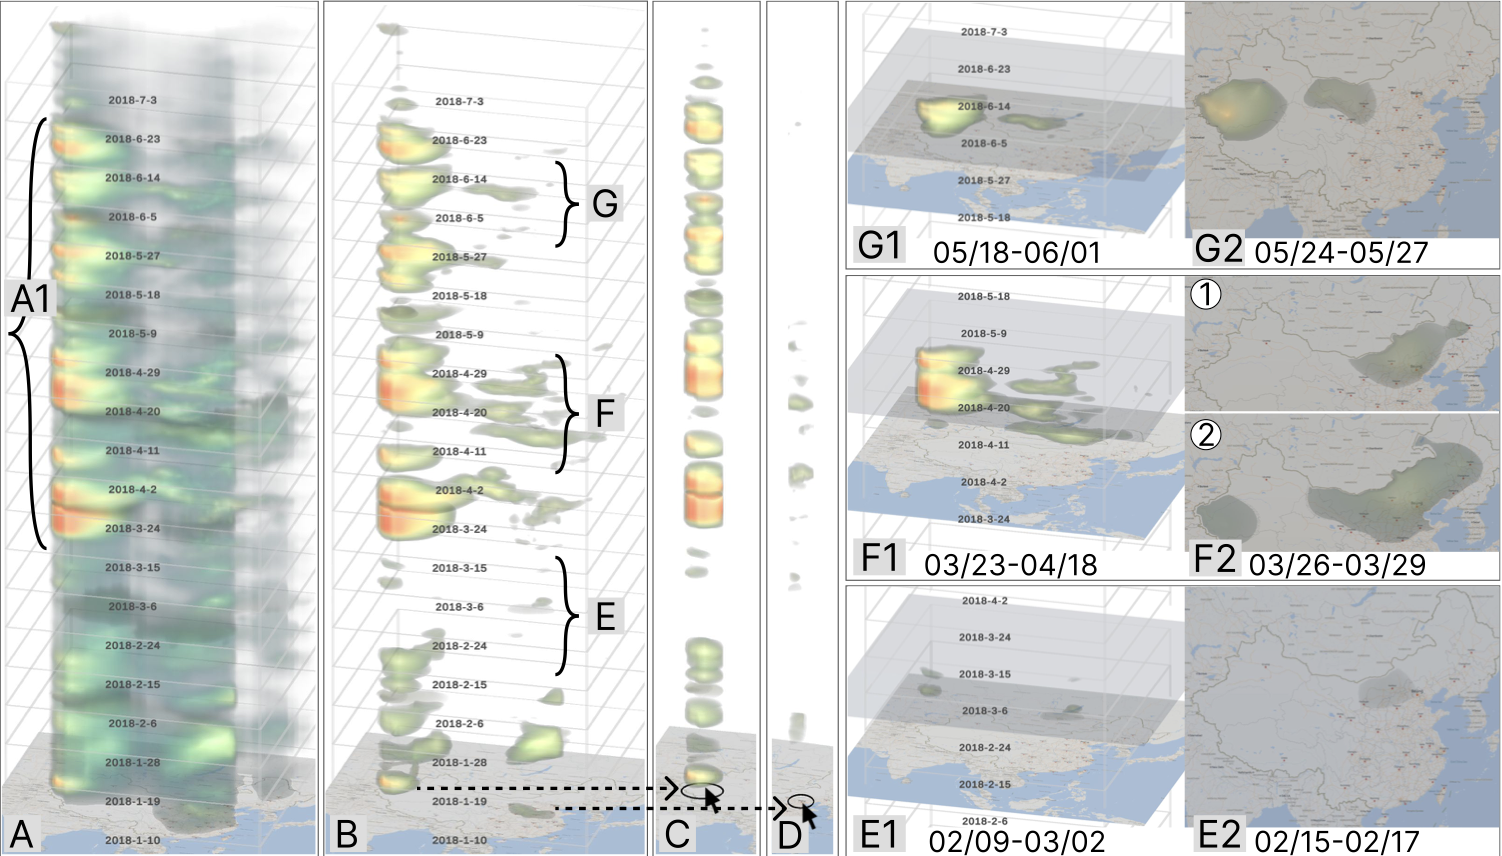
Volume-Based Space-Time Cube for Large-Scale Continuous Spatial Time Series
Zikun Deng, Jiabao Huang, , Jialing Li, Shaowu Gao, Yi Cai
IEEE Transactions on Visualization and Computer Graphics (TVCG)
A technique called VolumeSTCube, that incorporates a data transformation framework, volume visualization techniques, and tailored spatiotemporal interactions to visualize large-scale ST series in a spacetime cube effectively.
Volume-Based Space-Time Cube for Large-Scale Continuous Spatial Time Series
Zikun Deng, Jiabao Huang, , Jialing Li, Shaowu Gao, Yi Cai
IEEE Transactions on Visualization and Computer Graphics (TVCG)
A technique called VolumeSTCube, that incorporates a data transformation framework, volume visualization techniques, and tailored spatiotemporal interactions to visualize large-scale ST series in a spacetime cube effectively.